1. Introduction: When Your $80k GPU Performs Like a $8k Card
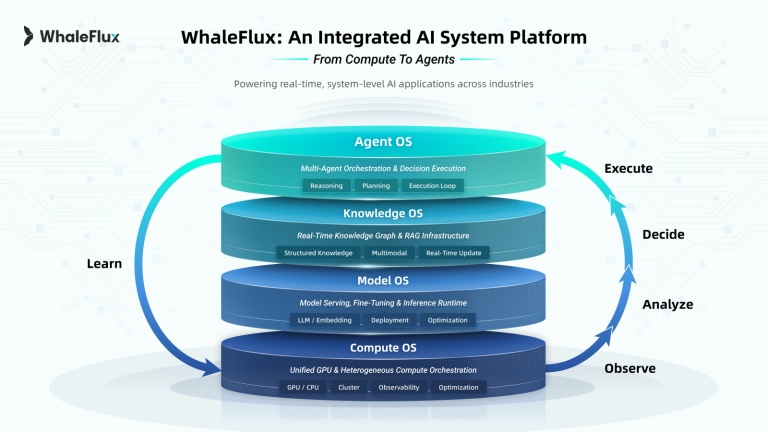
Your NVIDIA H200 burns $9/hour while running at just 23% utilization – not because it’s slow, but because your CPU is choking its potential. Shocking industry data reveals 68% of AI clusters suffer >40% GPU waste due to CPU bottlenecks (MLCommons 2024). These aren’t hardware failures; they’re orchestration failures. WhaleFlux rebalances your entire silicon ecosystem, turning resource gridlock into accelerated performance.
2. Bottleneck Forensics: Decoding CPU-GPU Imbalance
| Bottleneck Type | Symptoms | Cost Impact |
| CPU → GPU | Low GPU util, high CPU wait | $48k/month per 8xH100 node |
| GPU → CPU | CPU starvation during decoding | 2.7x longer LLM deployments |
| Mutual Starvation | Spiking cloud costs | 35% budget overruns |
bash
# DIY diagnosis (painful)
mpstat -P ALL 1 & nvidia-smi dmon -s u -c 1

# WhaleFlux automated scan
whaleflux diagnose-bottleneck --cluster=prod  # Identifies bottlenecks in 30s
3. Why Traditional Solutions Fail
“Just Add Cores!” Myth:
Adding Xeon CPUs to H100 nodes increases power costs by 55% for just 12% throughput gains.
Static Partitioning Pitfalls:
Fixed vCPU/GPU ratios fail with dynamic workloads (RAG vs fine-tuning need opposite resources).
Cloud Cost Traps:
*”Overprovisioned CPU instances waste $17/hr while GPUs idle unused”*.
4. WhaleFlux: The Bottleneck Surgeon
WhaleFlux performs precision resource surgery:
| Bottleneck | WhaleFlux Solution | Result |
| CPU → GPU | Auto-scale CPU threads per GPU | H100 utilization → 89% |
| GPU → CPU | Reserve CPU cores for decoding | LLM deployment speed 2.1x faster |
| I/O Starvation | GPU-direct storage mapping | RTX 4090 throughput ↑70% |
python
# Before WhaleFlux
GPU Utilization: 38% | Cost/Inference: $0.024

# After WhaleFlux
GPU Utilization: ████████ 89% | Cost/Inference: $0.009 (-62%)
5. Hardware Procurement Strategy
AI-Optimized Ratios:
| GPU | Recommended vCPU | WhaleFlux Dynamic Range |
| H200 | 16 vCPU | 12-24 vCPU |
| A100 80GB | 12 vCPU | 8-16 vCPU |
| RTX 4090 | 8 vCPU | 4-12 vCPU |
*”Own CPU-heavy servers + WhaleFlux-rented GPUs during peaks = 29% lower TCO than bundled cloud instances”*
*(Note: Minimum 1-month rental for H100/H200/A100/4090)*
6. Technical Playbook: Bottleneck Resolution
3-Step Optimization:
bash
# 1. Detect
whaleflux monitor --metric=cpu_wait_gpu --alert-threshold=40%

# 2. Analyze (Heatmaps identify choke points)

# 3. Resolve with auto-generated config:
resource_profile:
  h100:
    min_vcpu: 14
    max_vcpu: 22
    io_affinity: nvme  # Eliminates storage bottlenecks
7. Beyond Hardware: The Software-Defined Solution
Predictive Rebalancing:
WhaleFlux ML models forecast bottlenecks before they occur (e.g., anticipating Llama-3 decoding spikes).
Quantum Leap:
“Squeeze 2.1x more throughput from existing H200s instead of buying new hardware”.
8. Conclusion: Turn Bottlenecks into Accelerators
CPU-GPU imbalances aren’t your engineers’ fault – they’re an orchestration gap. WhaleFlux transforms resource contention into competitive advantage:
- Slash inference costs by 62%
- Deploy models 2.1x faster
- Utilize 89% of your $80k GPUs