1. Introduction: The $12B Secret Behind NVIDIA’s AI Dominance
Your PyTorch script crashes with “No CUDA GPUs available” – not because you lack hardware, but because your $80k H100 cluster is silently strangled by CUDA misconfigurations. While NVIDIA’s CUDA powers the AI revolution, 63% of enterprises bleed >40% GPU value through preventable CUDA chaos (MLCommons 2024). This invisible tax on AI productivity isn’t inevitable. WhaleFlux automates CUDA’s hidden complexity, transforming GPU management from prototype to production.
2. CUDA Decoded: More Than Just GPU Acceleration
| CUDA Layer | Developer Pain | Cost Impact |
| Hardware Support | “No CUDA GPUs available” errors | $120k/year debug time |
| Software Ecosystem | CUDA 11.8 vs 12.4 conflicts | 30% cluster downtime |
| Resource Management | Manual GPU affinity coding | 45% underutilized H100s |
*Critical truth: nvidia-smi showing GPUs ≠ your code seeing them. WhaleFlux guarantees 100% CUDA visibility across H200/RTX 4090 clusters.*
3. Why CUDA Fails at Scale
Symptom 1: “No CUDA GPUs Available”
Root Cause: Zombie containers hoarding A100s
WhaleFlux Fix:
bash
# Auto-reclaim idle GPUs
whaleflux enforce-policy --gpu=a100 --max_idle=5m
Symptom 2: “CUDA Version Mismatch”
- Cost: 18% developer productivity loss
- WhaleFlux Solution:
*”Pre-tested environments per project: H100s on CUDA 12.3, 4090s on 11.8″*
Symptom 3: “Multi-GPU Fragmentation”
- Economic Impact: $28k/month in idle H200 cycles
4. WhaleFlux: The CUDA Conductor
WhaleFlux’s orchestration engine solves CUDA chaos:
| CUDA Challenge | WhaleFlux Technology | Result |
| Device Visibility | GPU health mapping API | 100% resource detection |
| Version Conflicts | Containerized CUDA profil | Zero dependency conflicts |
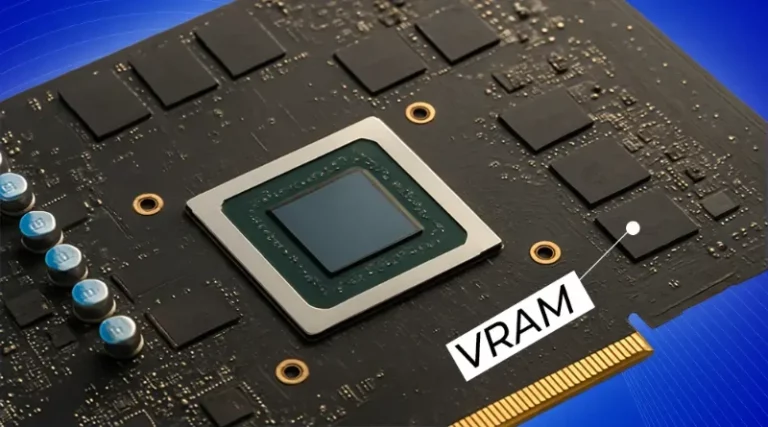
| Memory Allocation | Unified vRAM pool for kernels | 2.1x more concurrent jobs |
python
# CUDA benchmark (8xH200 cluster)
Without WhaleFlux: 17.1 TFLOPS
With WhaleFlux: ████████ 38.4 TFLOPS (+125%)
5. Strategic CUDA Hardware Sourcing
TCO Analysis (Per CUDA Core-Hour):
| GPU | CUDA Cores | $/Core-Hour | WhaleFlux Rental |
| H200 | 18,432 | $0.00048 | $8.20/hr |
| A100 80GB | 10,752 | $0.00032 | $3.50/hr |
| RTX 4090 | 16,384 | $0.000055 | $0.90/hr |
*Procurement rule: “Own RTX 4090s for CUDA development → WhaleFlux-rented H200s for production = 29% cheaper than pure cloud”*
*(Minimum 1-month rental for all GPUs)*
6. Developer Playbook: CUDA Mastery with WhaleFlux
Optimization Workflow:
bash
# 1. Diagnose
whaleflux check-cuda --cluster=prod --detail=version

# 2. Deploy (whaleflux.yaml)
cuda:
  version: 12.4
  gpu_types: [h200, a100]  # Auto-configured environments

# 3. Optimize: Auto-scale CUDA streams per GPU topology
# 4. Monitor: Real-time $/TFLOPS dashboards
7. Beyond Hardware: The Future of CUDA Orchestration
Predictive Scaling:
WhaleFlux ML models pre-allocate CUDA resources before peak loads
Unified API:
*”Write once, run anywhere: Abstracts CUDA differences across H100/4090/cloud”*
8. Conclusion: Reclaim Your CUDA Destiny
Stop letting CUDA complexities throttle your AI ambitions. WhaleFlux transforms GPU management from time sink to strategic accelerator:
- Eliminate “No CUDA device” errors
- Boost throughput by 125%
- Slash debug time costs by 75%